How to Measure Cause Marketing Without Fooling Yourself
Separate delivery, sentiment and sales; define commercial ROI, design credible comparisons and report uncertainty against the campaign’s break-even point.
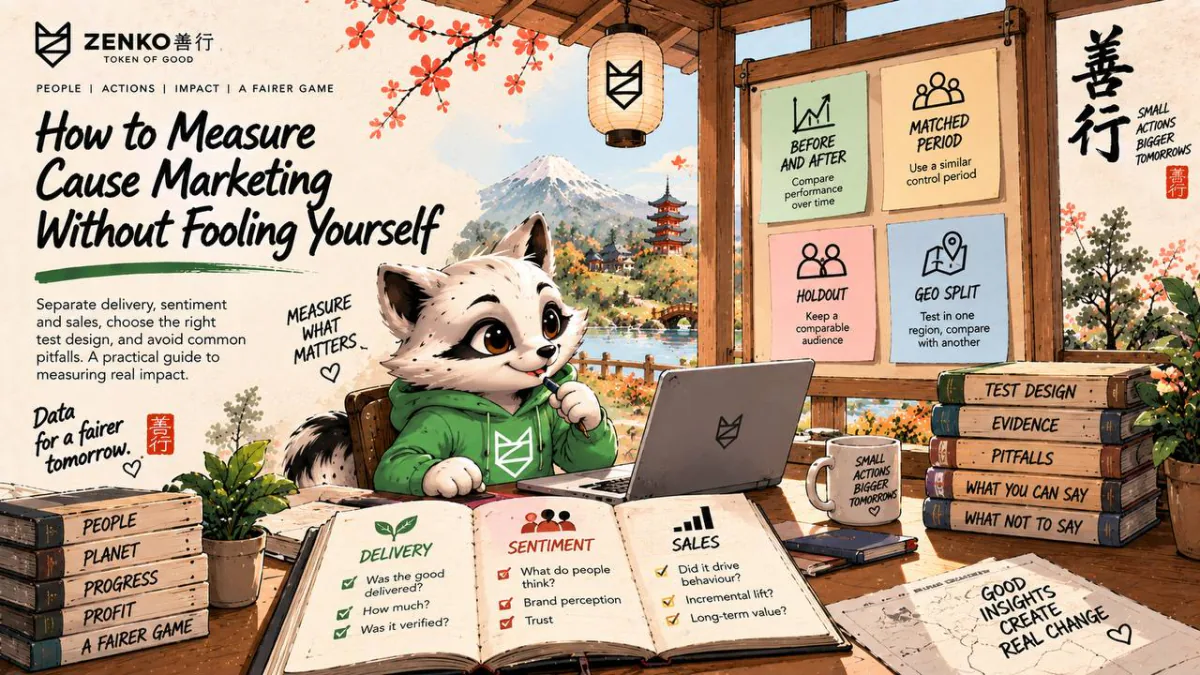
To measure cause marketing honestly, keep three questions apart: did the money or help reach the cause, did people's view of the brand change, and did you sell more than you would have anyway? Evidence for one does not by itself establish the others. A delivery claim can be mistaken for a return-on-investment claim.
This guide separates those questions, explains what the available research supports, sets out four comparison designs and defines a commercial ROI calculation. It is part of our wider guide to cause marketing. If you have not priced the promotion, start with the Cause Marketing Calculator: break-even gives you a commercial threshold to test, not evidence that you will reach it.
Three questions, three kinds of evidence
| Question | What it measures | Typical evidence | What it cannot establish by itself |
|---|---|---|---|
| Delivery | Did the money or help reach the cause? | Charity receipt, payment record, delivery report, dates and amounts | Additional sales, net profit or lasting recipient benefit |
| Sentiment | Did people's view of the brand change? | A consistent survey with a credible comparison, stated sample and uncertainty | Additional purchases or commercial payback |
| Sales | Did you sell more than you would have without the campaign? | A credible causal comparison, preferably randomised where feasible, with suitable analysis | Why people bought, whether the charity received the contribution, or whether recipients benefited |
A fourth question sits behind delivery: did the help work? A TOMS-supported cluster-randomised trial in rural El Salvador studied 1,578 children in 979 households. In a setting where most children already owned shoes, it found generally insignificant health and self-esteem effects and small positive school-attendance effects for boys; the researchers judged the overall effect negligible. That finding comes from the 2016 working-paper version, not a full review here of the later journal article. It does not show that every TOMS programme failed.
Delivery and recipient benefit need separate evidence. A small brand can ask its charity partner what it measures and report the answer accurately without claiming to have independently evaluated the programme.
What the research found
A 2023 meta-analysis of 237 studies reports a moderate average effect on attitudes (d = 0.458) and a smaller average effect on behavioural responses (d = 0.283), with high variation between studies. These are standardised effect sizes, not percentage sales lifts. The authors identify visual prominence of the donation as the strongest individual moderator of behavioural responses; the priorities for attitudes and behaviour differ.
A separate 2024 field study of 63 cause-related promotions across 20 fast-moving consumer goods categories reports a 4.9% average weekly sales lift, a 3.2% average donation as a share of product price and an 11-week average campaign duration. These sample averages are not a forecast for your business, a ceiling on possible results or a recommended donation rate. In the American Marketing Association interview dated 25 September 2025, the researchers emphasise wide variation and say some campaigns substantially outperform the average.
This account uses verified university-hosted abstracts and the separately attributed AMA interview. It is not a full review of the two journal papers' methods. We do not claim exact proportions of laboratory studies or purchase-intention measures, a dataset country or internal page-level findings that those accessible sources do not establish.
For a small brand, the practical question is not whether your result matches 4.9%. It is whether the campaign's estimated additional contribution covers its full cost, and whether your test can distinguish that result from ordinary variation. That is a planning inference, not an additional finding from the papers.
Four test designs, and where each breaks
The purpose of a comparison is to estimate the counterfactual: what would have happened without the campaign. HM Treasury's Quality in Policy Impact Evaluation distinguishes strong experimental and quasi-experimental designs from weaker unmatched and before-and-after comparisons. Its guidance concerns policy evaluation, but marketing has the same attribution problem.
Before and after. Compare campaign-period sales with a pre-set earlier period. This describes a change, not necessarily an effect of the campaign. Seasonality, prices, distribution, stock availability and other marketing can change at the same time. A large difference alone does not remove those explanations.
Matched period. Compare with a relevant earlier period, such as the same weeks last year. This can improve context but still lacks a concurrent untreated comparison. State what changed between periods, including product mix and distribution. Do not describe a matched historical period as a controlled experiment or assume it removes seasonal and market differences.
Randomised holdout. Randomly assign eligible customers, stores or other appropriate units before launch. Compare everyone assigned to the offer with everyone assigned to the holdout, not only those who chose to participate. Keep other treatment conditions comparable, plan enough volume to detect an effect that matters commercially, and check contamination and missing data. A non-random holdout can differ from the treatment group in ways that bias the result. Merely having a holdout does not make a result causal.
Geo experiment. Where delivery is geographic, use non-overlapping areas and, where feasible, match them using pre-campaign data before randomising treatment within pairs. Google researchers' work on randomised paired geo experiments highlights small samples, differences between areas, changing sales patterns and spillovers. One treated region versus one hand-picked comparison region is not automatically a convincing causal test. The introduction and background of the author preprint, pages 1–4, support this summary; it is not a claim to have evaluated every method in the paper.
Write down the assignment method, primary outcome, comparison, analysis window, cost boundaries and stopping rule before launch. Plan sample size around the smallest commercially meaningful effect, not a hoped-for headline number. Analyse at a level that respects the assignment: many customer purchases do not turn a small number of randomised stores into many independent experimental units.
Report an uncertainty interval alongside the estimated sales effect and explain the method used to calculate it. Small samples may leave a wide interval even when the point estimate looks promising. If randomisation is impossible, a defensible quasi-experimental design may help, but its assumptions and threats to validity must be stated. A specialist can help assess whether those assumptions are credible.
For the wider approach we use for rewards-based programmes, see how to measure a rewards-based campaign. To compare customer groups over time, see cohort analysis. Cohort tracking is useful, but it does not remove selection bias on its own.
Common pitfalls
Seasonal sales. A rise during a busy trading period is not automatically a campaign effect. Account for the calendar and concurrent changes rather than treating an earlier quiet period as the counterfactual.
Attributing a combined offer to the donation alone. If a donation and a discount launch together, a simple before-and-after comparison cannot separate their effects. If volume permits, randomise customers or stores between no offer, donation only, discount only and both. Otherwise report the result as the effect of the combined offer. In the AMA interview, the field-study researchers describe price promotions as potentially complementary to cause promotions; that is not a reason to attribute the entire combined lift to the donation.
Selection bias. People who choose to participate, claim a donation or follow cause-related posts can differ from those who do not. Comparing participants with everyone else can measure those pre-existing differences rather than the campaign. In a randomised test, keep participants in their assigned groups for the primary analysis, whether or not they took up the offer.
Counting a donation twice. A donation is a cost and, once paid and documented, evidence of delivery. It is not evidence of sales. In a commercial calculation, count each cost once and include donations on sales that would have happened without the campaign, not only the estimated additional sales.
Reporting revenue as return. More sales revenue does not mean an equivalent increase in profit. Product costs, discounts, returns, donations and campaign costs can change the result. Define the accounting basis and use contribution, not revenue, in the payback calculation.
What good delivery evidence looks like
For the delivery question, evidence should be specific and checkable:
- the amount paid, date and payment record;
- confirmation from the recipient that it received the contribution, and its report of use where available;
- the promotion period, eligible sales or actions, contribution calculation and any reconciliation;
- for a delivery quantity such as fresh produce, the delivery partner's report and the basis used to describe the quantity.
Agree reporting before launch. Payment, allocation, delivery and recipient benefit are separate stages; a receipt alone does not show what was delivered or its lasting effect. If a partner reports a meal-equivalent quantity, do not turn it into a count of meals eaten without supporting evidence.
For an England and Wales agreement that falls within the statutory commercial participator rules, section 59(7) of the Charities Act 1992 requires arrangements enabling the charity to monitor compliance, alongside the other prescribed agreement requirements. This is not a blanket requirement triggered merely by mentioning a charity. The relevant test concerns the business, promotional venture and representation of charitable contributions under section 58. Other jurisdictions and partnerships need their own checks. See how to choose a charity partner and the UK commercial participator rules.
Zenko's own programme illustrates the distinction. Zenko reports that the MK Dons Shop for Good programme delivered 2,000 meals' worth of fresh produce. This is a reported delivery quantity, not a count of meals eaten, children permanently supported, additional shirt sales or net profit. We do not present it as a sales-lift or commercial ROI result.
Zenko describes Shop for Good as connecting an eligible purchase to a separately funded outcome delivered by a named local partner, with a record of participation. Its verified-action model checks that a specified purchase, course or activity happened before releasing a reward. These are related mechanisms, not proof that every action automatically produces a charitable outcome. The funder, eligibility, contribution and delivery evidence need to be agreed for each programme.
How to calculate commercial ROI
Define the cost boundary before using the term ROI. For this guide:
Incremental campaign contribution = estimated extra sales × gross contribution per sale − total campaign donation − other campaign costs.
Commercial ROI = incremental campaign contribution ÷ (total campaign donation + other campaign costs).
Multiply that ratio by 100 to express a percentage. Other reports use different denominators, so state this definition wherever you report the result. Here, gross contribution per sale is the planning amount derived from selling price excluding VAT or sales tax and the gross-margin percentage, before the campaign's donation and other costs. It is not net profit. Use consistent accounting inputs and include relevant additional variable costs when adapting the model. Avoid subtracting the same cost both within contribution and again as a campaign cost.
The donation total includes donations on baseline sales as well as extra sales. If the donation changes with total sales, a cap or a guaranteed minimum, calculate it under the actual terms rather than treating it as a fixed amount without checking. A calculator's cap scenario is not approved advertising wording: CAP rule 8.33.5 restricts cut-offs for consumer contributions where an amount is stated for each purchase. Disclosure of a cap is not by itself approval of an every-purchase promise.
A worked example: £2,500 divided by £7,500
This is a hypothetical planning example, not a forecast or a Zenko campaign result. Suppose a credible test estimates 500 extra sales above 5,000 baseline sales during the same campaign period. The net selling price is £40, gross margin is 50%, the donation is £1 on each of all 5,500 sales and other campaign costs are £2,000.
| Item | Calculation | Amount |
|---|---|---|
| Gross contribution per sale | £40 × 50% | £20 |
| Additional gross contribution | 500 × £20 | £10,000 |
| Total campaign donation | 5,500 × £1 | £5,500 |
| Other campaign costs | Stated assumption | £2,000 |
| Incremental campaign contribution | £10,000 − £5,500 − £2,000 | £2,500 |
| Campaign investment under this definition | £5,500 + £2,000 | £7,500 |
| Commercial ROI | £2,500 ÷ £7,500 × 100 | 33.3% |
The example excludes overhead changes, tax and longer-term effects. It assumes the stated contribution and campaign-cost inputs are complete for its scope. An actual report should identify any further costs or effects rather than calling this limited calculation net profit.
Under these uncapped, no-minimum assumptions, break-even is 369 extra whole sales: (£2,000 + 5,000 × £1) ÷ (£20 − £1), rounded up. The donation on baseline sales is why the calculation is not simply £2,000 divided by £20.
The 500-extra-sales estimate also needs an uncertainty interval from the test. A point estimate of 33.3% ROI is not a guarantee. Carry the uncertainty through the contribution calculation, using the actual donation and cost rules. If the plausible incremental-sales range crosses break-even, the test does not clearly establish payback.
What you can claim, and what you cannot
| You can say, if you have the evidence | You should not say |
|---|---|
| “We gave £5,000 to [charity] during December”, supported by records | “Our donation proves the campaign increased sales” |
| “X of Y respondents noticed the campaign”, with sampling method and dates | “Customers love brands that support causes” based on that sample alone |
| “Sales were X% higher than in the matched period last year”, with comparability limits | “The campaign caused an X% increase” without a credible causal design, suitable analysis and uncertainty reporting |
| “Our randomised test estimates X additional sales, with this uncertainty interval”, including relevant limitations | “A holdout proves causation” merely because a comparison group existed |
| “The charity reports that the money funded [specific item or activity]” | “Every pound produced this lasting benefit” without evidence supporting that causal claim |
| “Under our stated cost definition, estimated commercial ROI was X%, with these limitations” | “Net profit rose by X” when the calculation only measures incremental campaign contribution |
A non-random holdout can support an analysis only if its causal assumptions are defensible. Randomisation is stronger protection against selection bias, but poor implementation, spillovers or unsuitable analysis can still undermine a test.
A simple scorecard
At the end of the campaign, report four lines side by side:
- Delivered: amount or quantity, date, source and proof; distinguish promised, paid and delivered support.
- Cost: total donation, including baseline sales, plus other campaign costs and the accounting boundaries used.
- Sales effect: estimated incremental sales, comparison design, uncertainty interval and limitations, not just the observed change in sales.
- Payback: break-even against the incremental-sales estimate and its uncertainty; incremental campaign contribution and commercial ROI under the stated definition.
If the estimated additional sales are below break-even, the point estimate indicates a commercial shortfall within the model. If the uncertainty interval spans break-even, the test does not clearly establish whether the campaign paid back. If the estimate and its uncertainty interval are above the threshold, that supports payback within the stated assumptions, not a guarantee for the next campaign.
A business can choose to fund a programme for reasons other than short-term commercial return. Report that choice honestly. Delivered food is not commercial ROI, and sales revenue is not net profit.
FAQs
How do you measure the ROI of cause marketing?
Estimate additional sales using a credible comparison, then calculate incremental campaign contribution: extra sales × gross contribution per sale, minus the total donation and other campaign costs. This guide defines commercial ROI as that contribution divided by the donation plus other campaign costs. Include donations on baseline sales and report uncertainty. In the hypothetical example, £2,500 divided by £7,500 gives 33.3%, not a forecast or net-profit result.
Does cause marketing increase sales?
Results vary substantially. A 2024 study of 63 cause-related promotions reports a 4.9% average weekly sales lift, a 3.2% average donation and an 11-week average duration. Those sample averages are not a forecast, ceiling or recommended donation rate. This guide summarises verified abstracts and a later AMA interview, not a full review of the journal papers' methods. Test your own commercial result.
What is the simplest way for a small brand to test it?
A pre-set comparison with the same weeks last year can describe a change, but cannot isolate the campaign from other changes. Where feasible, randomly assign eligible customers or stores to an offer and a holdout, plan enough volume and analyse everyone as assigned. Report uncertainty. A non-random holdout or one hand-picked comparison region is not automatically a causal test.
What evidence of delivery should a charity partner provide?
Agree reporting before launch: payment amounts and dates, confirmation of receipt, the eligible sales or actions and contribution calculation, and the partner's account of use or delivery where available. Distinguish payment from delivery and lasting benefit. A reported meal-equivalent quantity is not automatically a count of meals eaten or evidence of commercial return.
Can I say my charity campaign increased sales?
A causal claim needs a credible design, suitable analysis and uncertainty reporting. A randomised holdout can help, but merely having a comparison group is insufficient. A matched historical period supports a statement about the observed difference with its limitations, not necessarily causation. Delivery records alone cannot show additional sales, and additional revenue alone cannot establish profit.
Why can consumer-response studies and real campaigns give different results?
They can measure different outcomes in different settings. A standardised attitude or behavioural-response effect is not a percentage sales lift. The 2023 meta-analysis reports substantial variation, and the field-study researchers emphasise variation between campaigns in their later AMA interview. Without a full-paper methods review, this guide does not claim exact proportions of laboratory or intention measures, or that real campaigns always perform worse.
Sources
Sources checked on 11 October 2026. The research summaries below distinguish verified abstracts, a later interview and the working-paper version actually used. Bibliographic page spans are not claims of pinpoint full-paper verification.
- Schamp, C., Heitmann, M., Bijmolt, T.H.A. and Katzenstein, R. (2023), “The Effectiveness of Cause-Related Marketing: A Meta-Analysis on Consumer Responses”, Journal of Marketing Research 60(1), 189–215. Verified university-hosted abstract: https://research.rug.nl/en/publications/e27de894-3b20-47b7-a3bf-53e080a093ee/ ; DOI: https://doi.org/10.1177/00222437221109782
- Schamp, C., Heitmann, M., Peers, Y. and Leeflang, P. (2024), “Cause-Related Marketing as Sales Promotion”, Journal of Marketing Research 61(5), 955–974. Verified university-hosted abstract: https://research.vu.nl/en/publications/c794eb2b-96ad-4608-9ffc-e8137f51d15e ; DOI: https://doi.org/10.1177/00222437231200807
- American Marketing Association, “Do Good, Sell More? Can Cause-Related Marketing Promotions Boost Product Sales?”, 25 September 2025. Separately attributed public interview. https://www.ama.org/2025/09/25/do-good-sell-more-can-cause-related-marketing-promotions-boost-product-sales/
- Wydick, B., Katz, E., Calvo, F., Gutierrez, F. and Janet, B., World Bank Working Paper WPS7822, September 2016. Working-paper version used for the trial account; acknowledges TOMS support. https://documents1.worldbank.org/curated/en/960091473863696457/pdf/WPS7822.pdf
- HM Treasury, Quality in Policy Impact Evaluation, including the summary of research designs and sections 1.6 and 1.12. https://www.gov.uk/government/publications/the-magenta-book/quality-in-policy-impact-evaluation-qpie-html
- Chen, A., Longfils, M. and Remy, N. (2021), Trimmed Match Design for Randomized Paired Geo Experiments. Introduction/background, preprint pages 1–4, used for the design cautions. https://research.google/pubs/trimmed-match-design-for-randomized-paired-geo-experiments/ ; author preprint: https://arxiv.org/pdf/2105.07060
- Charities Act 1992, section 58, commercial participator definitions. https://www.legislation.gov.uk/ukpga/1992/41/section/58
- Charities Act 1992, section 59(7) and (8), agreement and monitoring requirements. https://www.legislation.gov.uk/ukpga/1992/41/section/59
- CAP Code, section 8, including rule 8.33.5 on contribution cut-offs. https://www.asa.org.uk/type/non_broadcast/code_section/08.html
- Zenko, Cause Marketing Calculator. Planning model, not campaign evidence or advertising approval. https://www.zenkoprotocol.com/cause-marketing-calculator/
- Zenko, MK Dons Shop for Good delivery report. Reported delivery quantity, not a sales or net-profit study. https://www.zenkoprotocol.com/blog/more-than-2000-meals-for-milton-keynes-zenko-and-mk-dons-put-shop-for-good-into-action/
- Zenko, How Shop for Good Works, 23 July 2026. Product description. https://www.zenkoprotocol.com/insights/how-shop-for-good-works/
- Zenko, Verified Real-World Actions, 8 August 2026. Product description. https://www.zenkoprotocol.com/insights/verified-real-world-actions/
- Zenko, How to Measure a Rewards-Based Campaign. https://www.zenkoprotocol.com/insights/measure-rewards-based-campaign/
This article is general information, not legal, tax or accounting advice. It does not approve a campaign, agreement or advertising claim.